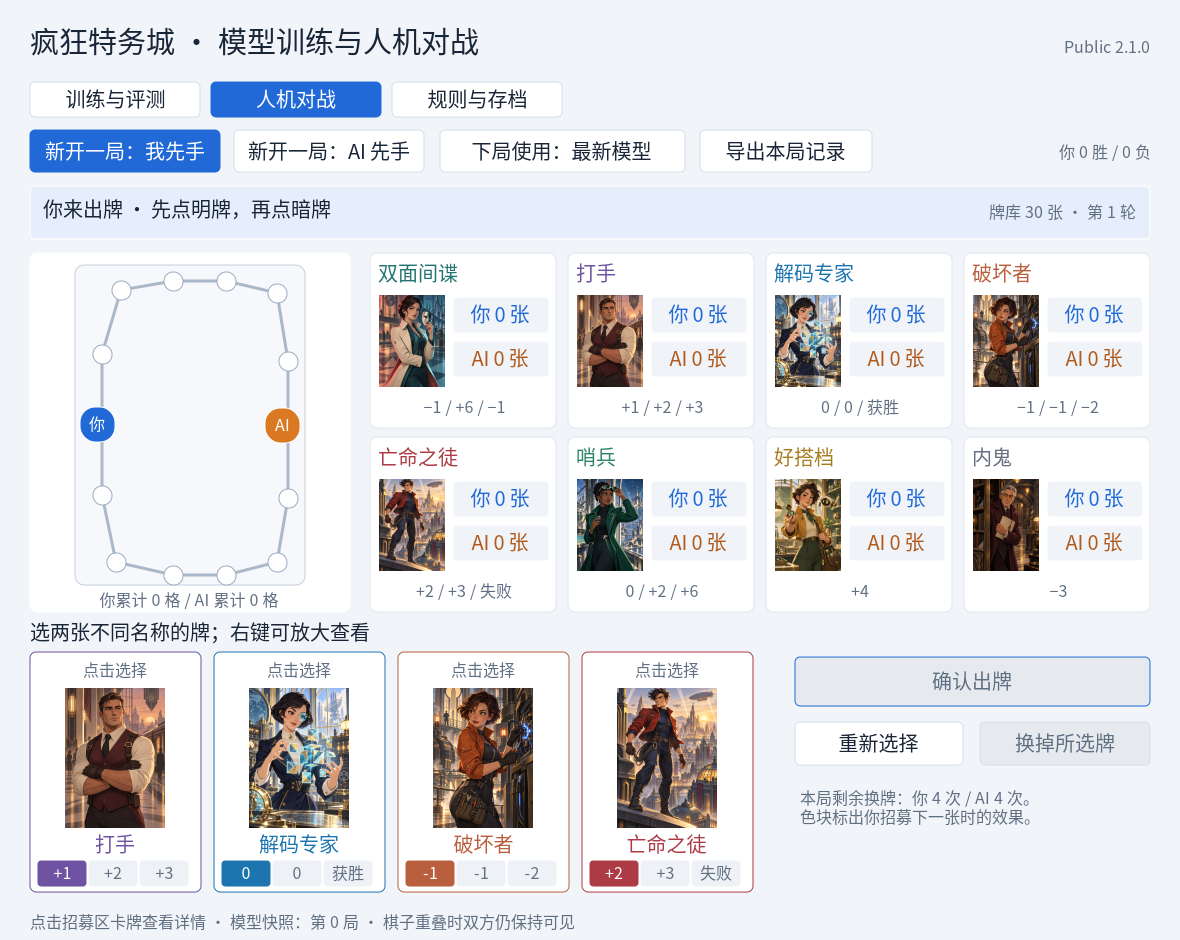
Hidden information
Player-specific 128-element observations exclude opponent hands, deck order, and the face-down offer. Illegal actions are masked across 74 policy outputs.
A self-play reinforcement-learning implementation for the hidden-information board game Agent Avenue. The repository includes the simulator, training pipeline, evaluation tools, checkpoints, and a Windows client.
The project is not an API wrapper or isolated model notebook. Training, evaluation, automated tests, and the desktop app share the same game state machine.
Player-specific 128-element observations exclude opponent hands, deck order, and the face-down offer. Illegal actions are masked across 74 policy outputs.
Deterministic CPU rollouts, optional CUDA/NVRTC updates, atomic saves, checksum validation, backup recovery, and exact training-state resume.
The frozen policy plays 5,000 games per opponent, balanced across first and second player, with methods and limitations documented publicly.
The release includes the 17M-game checkpoint and a native Windows client. Play in Chinese, English, or Spanish; inspect public cards; switch first player; and review why the game ended.